
SNACK: 3-line summary
- GitHub Copilot CLI can now discover supported models from a running local Ollama instance.
- Ollama and the model must already be installed, and the model needs both tool calling and streaming support.
- Selecting a local model does not automatically enable offline mode or disable GitHub telemetry.
GitHub Copilot CLI now lets you find compatible local Ollama models in its model picker and use one without restarting your session.

Snackgirls react
AIKO: When Auto arrives, I want to see which tasks it keeps local and which it sends to the cloud. Those decisions could be as interesting as the generated code.
Nea: I’d like to try this on a small personal coding project. Before I start, though, I want to know exactly where my code will be sent.
Choose a model without restarting
Starting with version 1.0.94-0, type /model inside GitHub Copilot CLI to see supported models from an already-running local Ollama instance alongside your configured models and GitHub Copilot’s cloud models. Local and external models were already supported through BYOK (Bring Your Own Key) provider configuration; the new feature is discovery in the picker.
Discovery does not add models automatically: select one, review its provider and endpoint, and confirm “Add and use for this session” or “Add without switching.” You can use the selected model in the current session without restarting the CLI.
Have Ollama and a compatible model ready
Ollama and the model you want must already be installed. The discovery flow does not install the runtime or download model weights.
Models need both tool calling, also known as function calling, and streaming support. If a provider connection fails, the picker displays an explanation to help you identify what needs attention.
Local inference is not an offline switch
Choosing a local model does not enable offline mode or disable GitHub telemetry. To prevent the CLI from contacting GitHub’s servers, set COPILOT_OFFLINE=true separately; full network isolation also requires a provider that is local or within the same isolated environment. If you configure a remote provider, your prompts and code context still go to that provider over the network, even with the offline flag set.
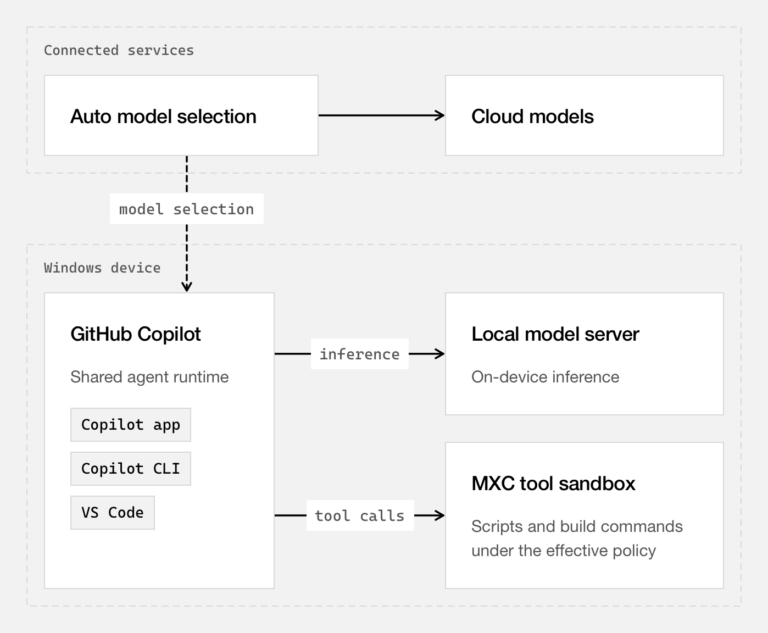
Microsoft has also announced intelligent Auto orchestration that can route work between local and cloud models, with availability planned by the end of October 2026. That is a separate upcoming feature, not something /model enables today.
Sources and checked date: October 8, 2026
Comments
0No login needed. Edit or delete your comment from the same browser.
All comments 0
한국어 · English · 日本語No comments yet. Start the conversation.